All articles
Page 7 of 12
Flat AI Pricing Is a Subsidy: One User Burned $30,983 of Tokens on a $200 Plan
Flat AI subscriptions only work while heavy users stay rare: one developer consuming roughly $30,983 of token value on a $200 per month plan is about a 155x gap between what was paid and what it cost to serve.
 LLM Economics
OpenAI's GPT-5.6 Price Cut: What Luna at $0.20 and Terra at $2 Do to Your Margins
Starting July 30, 2026, GPT-5.6 Luna costs $0.20 per 1M input tokens and $1.20 per 1M output tokens (an 80% cut), and Terra costs $2 and $12 (a 20% cut), which means the biggest saving for most teams comes from re-routing workloads rather than from the discount itself.
 LLM Economics
Cheaper Tokens Do Not Equal Better Margins: What GPT-5.6's Efficiency Push Means for Your AI Unit Economics
Provider efficiency gains only reach your P&L if your own architecture captures them: your prompt-cache hit rate, your agent loop length, and your model tiering decide whether a 20% serving-cost cut becomes 20% of margin or nothing at all.
 Pricing Strategy
What Cursor's $7 India Plan Teaches AI SaaS Founders About Geographic Pricing
Cursor just launched a roughly $7-a-month India-only plan, a third of its $20 Pro price, and the trick that makes it sustainable is routing those users to its own cheaper models instead of frontier third-party ones.
 LLM Economics
Claude Opus 5 vs Fable 5: What the Half-Price Flagship Means for Your LLM Cost Model
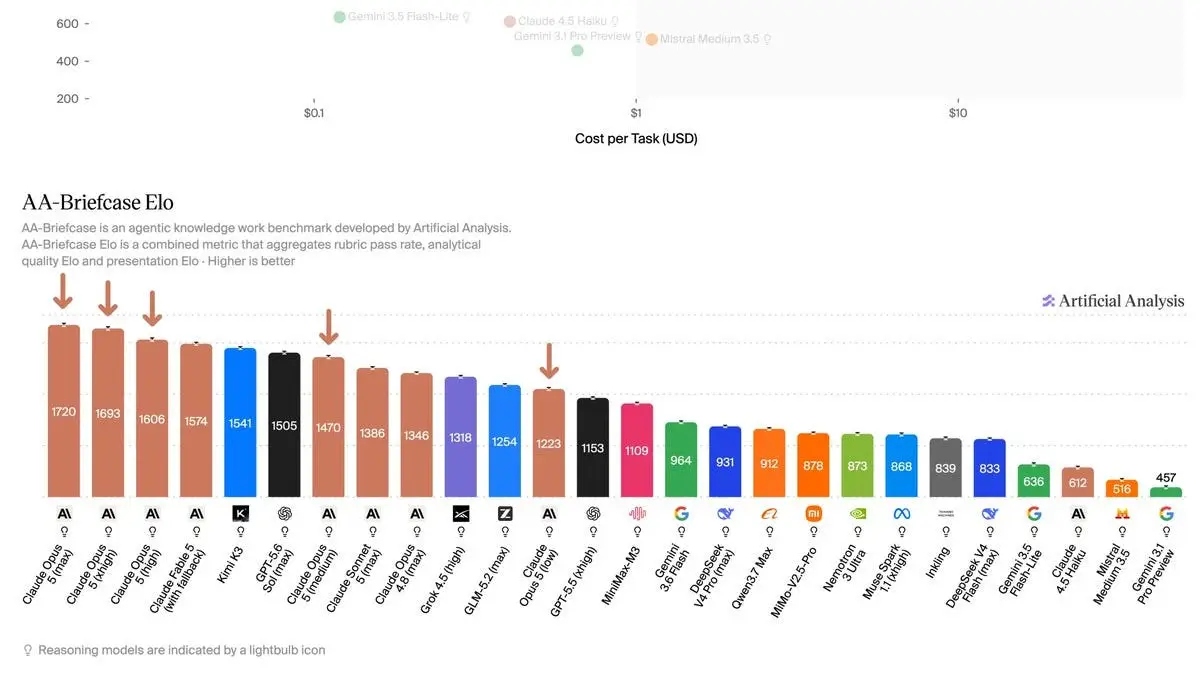
Anthropic's Claude Opus 5 lands within a few benchmark points of Fable 5 at roughly half the price, and independent testing shows a 20% lower cost per task, a shift worth rerunning your margin math over.
 LLM Economics
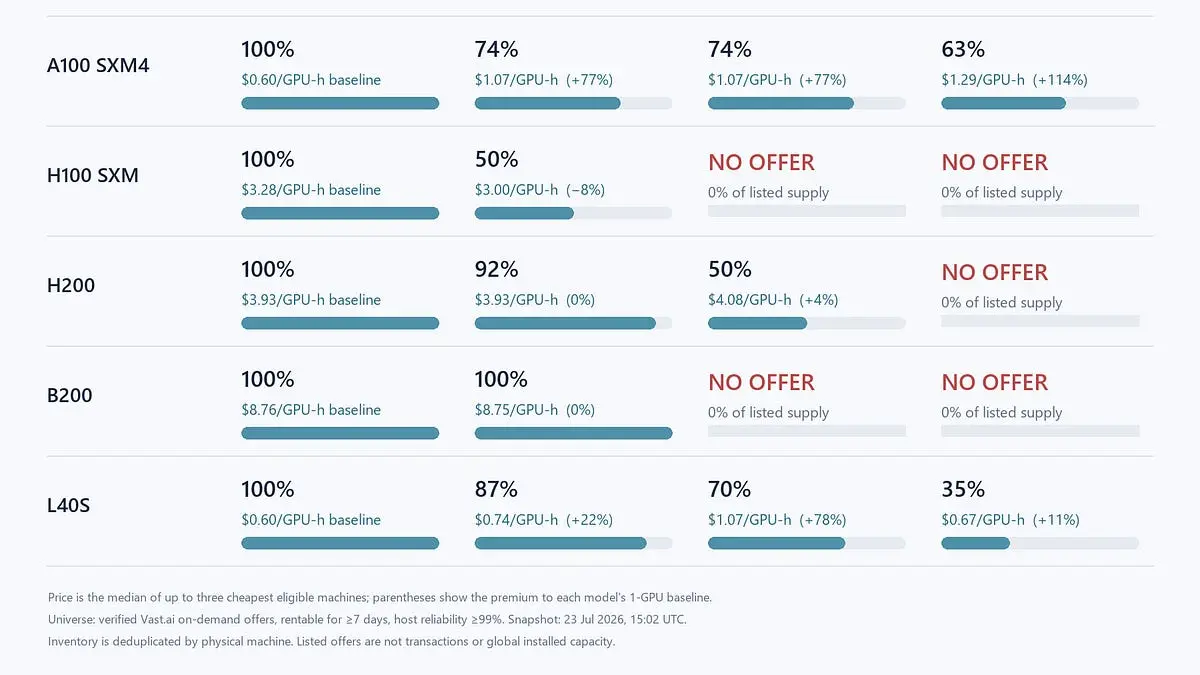
Why the GPU-Hour Sticker Price Isn't What You'll Pay for AI Inference at Scale
Headline GPU and LLM token prices describe what one unit costs, not what a usable amount of compute costs once you need it delivered together, on time, and at your scale.
 Pricing Strategy
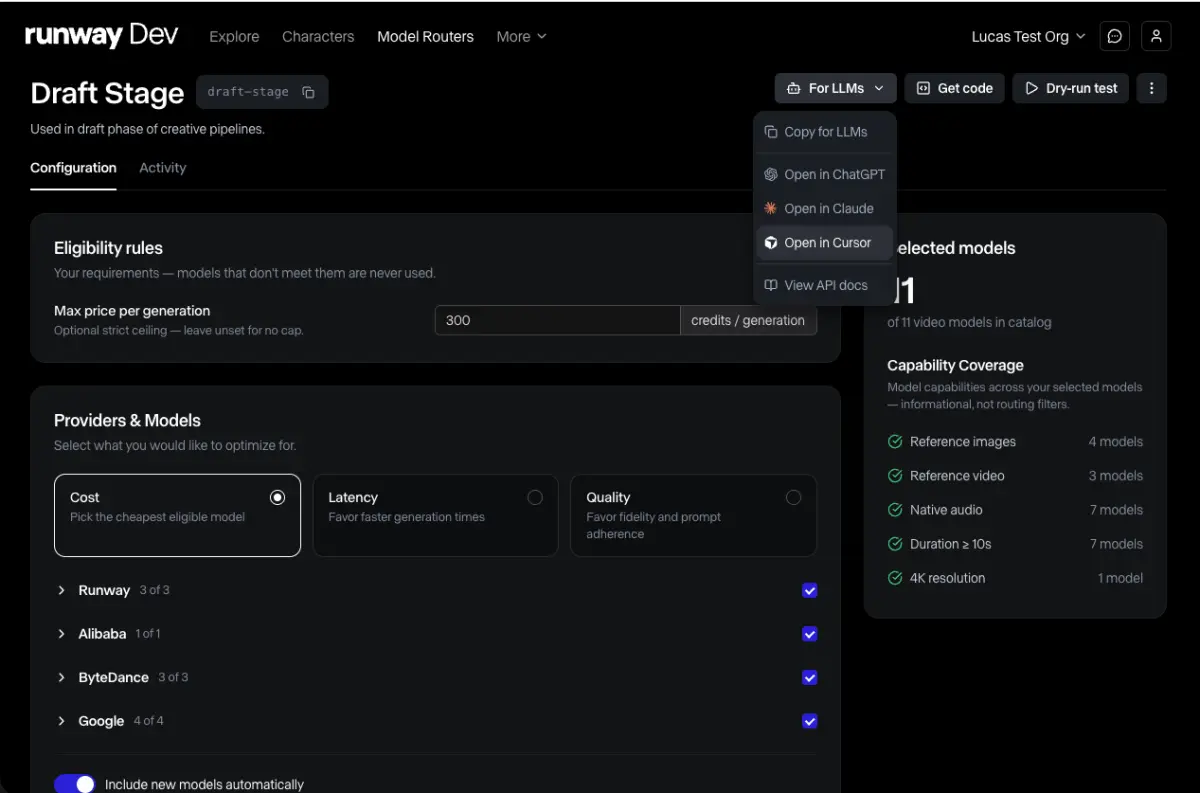
Runway's Pivot From 'Best Model' to 'Best Router' Is a Pricing Story
Runway just launched a router that picks the cheapest or best generative-media model per request, weeks after swapping its unlimited plans for token-based pricing, a two-part playbook worth studying if your own product depends on someone else's model.
 LLM Economics
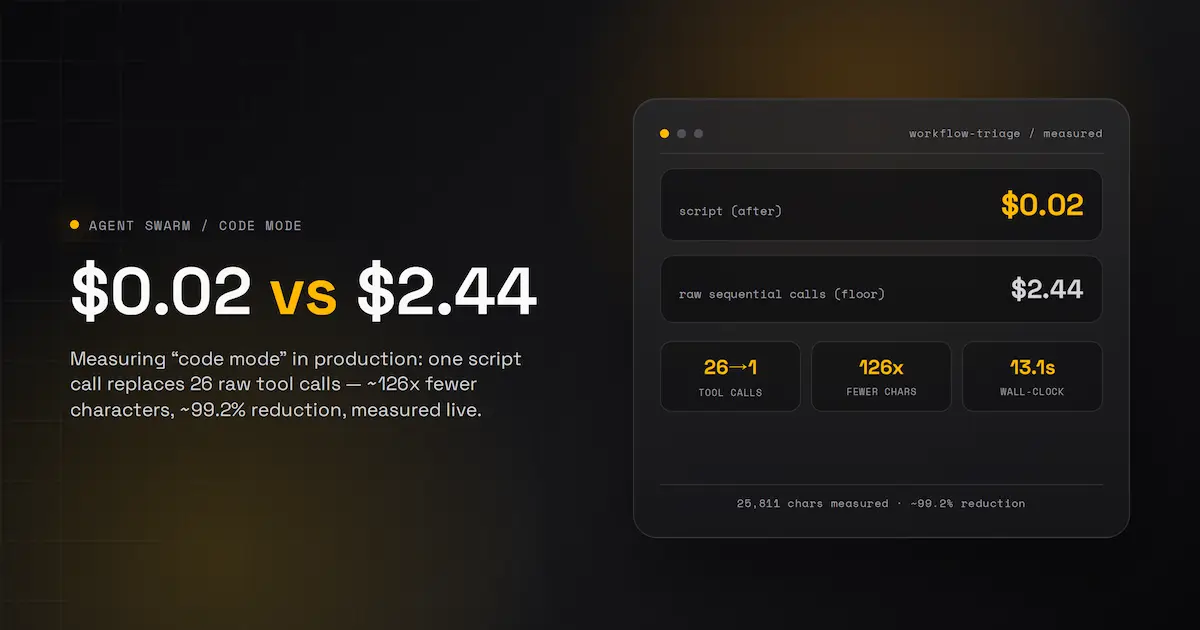
One Script, 26 Tool Calls, 99.2% Cheaper: What 'Code Mode' Really Saves
A production measurement from Agent Swarm shows that letting an agent run one script instead of 26 sequential tool calls cut a real workflow from an estimated $2.44 floor down to about two cents, and the saving dwarfs any difference between LLM providers.
 Product Updates
Claude Opus 5's Price Didn't Change, But Your Cost-Per-Task Probably Just Dropped
Opus 5 launches at the same $5/$25 per million token price as its predecessor, but Anthropic's own benchmarks suggest it needs fewer tokens and fewer retries to hit the same result, which is the number that actually matters for your margins.
Do AI Model Routers Actually Cut Your LLM Bill by Two-Thirds?
A Show HN launch claims routing across open-weight models delivers Fable-level output at roughly one-third the cost, but the real savings depend on your task mix and whether you keep your prompt cache intact.
 LLM Economics
Why AI Inference Costs Are Becoming the Real Battleground for SaaS Margins
AI inference, not training, is now the line item that will make or break your SaaS margins, because unlike training it is a per-query operating cost that scales with every user action.
 LLM Economics
Gemini 3.6 Flash Pricing: What $1.50/$7.50 Per Million Tokens Means for Agent Margins
Google's new Gemini 3.6 Flash costs $1.50 per 1M input tokens and $7.50 per 1M output tokens, undercutting 3.5 Flash on price while using roughly 17% fewer output tokens per task, a combination that compounds into a bigger margin gain than the sticker price alone suggests.
Pricing math, in your inbox.
One short note a week on AI pricing, token economics, and margin. No spam, unsubscribe anytime.