Founder Guides
Practical playbooks for SaaS founders modeling cost, trials, and margin.
 Founder Guides
How to Cut Agent Token Spend by 80% Without Changing Models
A practitioner reports cutting token spend on dynamic agent workflows by roughly 80% through prompt and workflow restructuring alone, which points at an uncomfortable truth: most agent spend is not on the task, it is on context you resend by default.
 Founder Guides
Log-Scale Pricing Charts Are Quietly Wrecking Your Model Choice
The intelligence-versus-cost chart everyone quotes uses a logarithmic price axis, which compresses a 50x difference into a couple of centimetres and makes wildly different bills look like neighbours.
 Founder Guides
I Modeled What $20,000 a Month on Devin Actually Buys a Solo Founder
A solo founder's public breakdown of spending $20,000 in a month on the Devin coding agent is a useful stress test for how any founder should think about AI-agent ROI, not just whether the number sounds high.
 Founder Guides
LLM VRAM Sizing: Your Context Limit Is a Pricing Decision
Llama 4 Scout needs about 231 GB of VRAM at a 1,024-token context and about 3,671 GB at its advertised 10M-token window, so the context length you configure sets your hardware bill more than the model size does.
 Founder Guides
How to Cut AI Agent Costs Without Downgrading Your Product
The largest cost lever in an AI agent is no longer which model you call, it is where you draw the line between work that needs judgement and work that only needs data moved.
 Founder Guides
Idle GPUs Are the Most Expensive Line in Your AI Budget
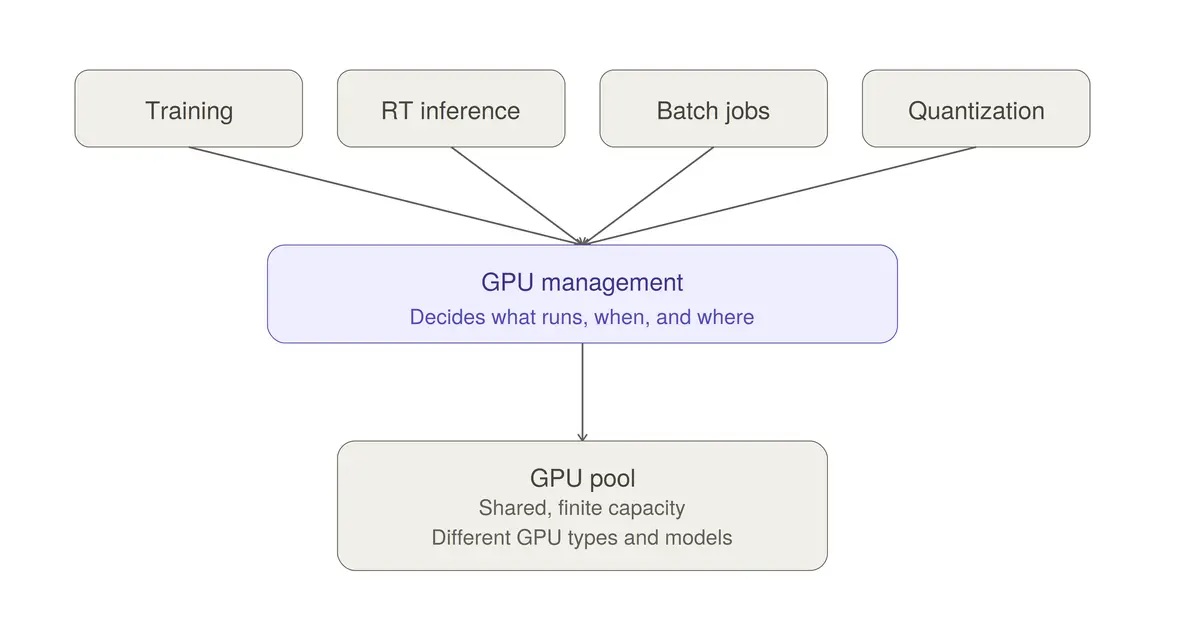
An owned GPU bills you by the calendar hour but only earns by the compute hour, so the utilisation number you assume in your build-versus-buy spreadsheet quietly decides whether the whole decision was right.
 Founder Guides
How to Manage AI Spend in the Agentic Era: A Founder's Playbook
OpenAI's new enterprise guidance says to stop staring at token prices and start measuring useful work per dollar; for a founder, that shift is the difference between guessing your margins and knowing them.
 Founder Guides
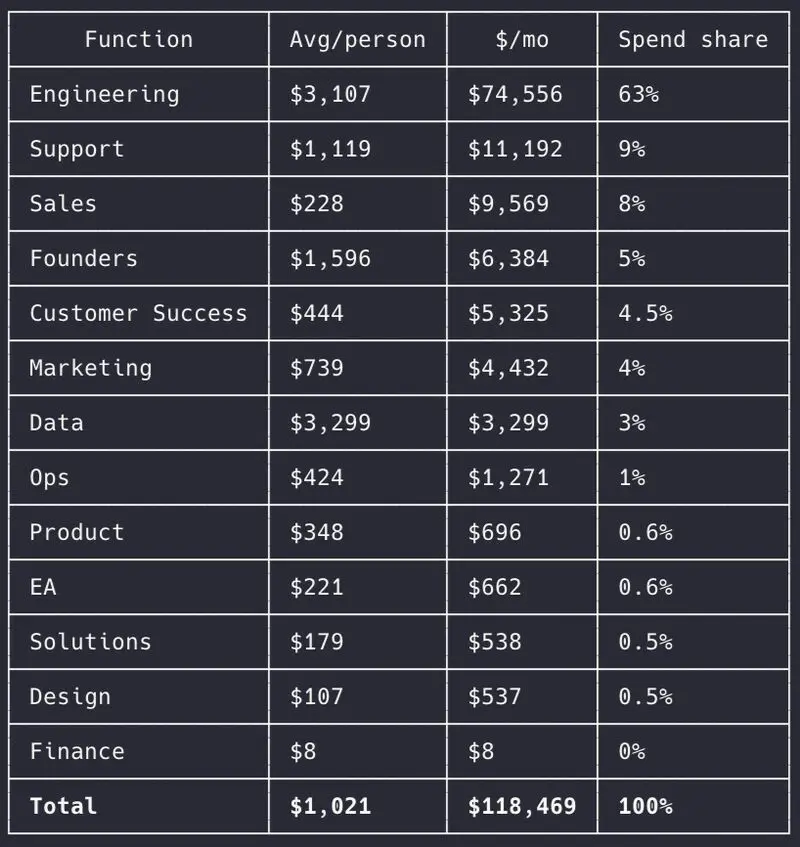
The AI Cost Crisis Is Self-Inflicted: How to Control LLM Spend Without Killing Adoption
Most runaway AI bills come from panic-driven defaults rather than workload needs, and a five-step governance framework can pull spend back without slowing adoption.
 Founder Guides
LLM Cost Optimization for Founders: Finding the 40-60% of Token Spend You Are Wasting
Field audits cited by TrueFoundry suggest 40-60% of production LLM token budgets go to redundant calls, oversized models, and ungoverned pipelines, and most of that waste can be located with an afternoon of log analysis.
 Founder Guides
GLM 5.2 vs Opus: Should You Swap Your Coding Model to Cut Costs?
Swapping a premium model like Opus for a cheaper open-weight model like GLM 5.2 can cut your AI bill sharply, but only if it clears the quality bar for the specific work you actually run.
 Founder Guides
How to Stop Your Team From Burning the AI Budget (Without Banning It)
The durable fix is not rationing tokens after the overspend, it is modeling cost per task up front so every team gets a budget tied to real unit economics.
 Founder Guides
Self-Hosting vs API: When Local LLMs Actually Cost Less
Local open models can run inference at near-zero marginal cost when you reuse hardware you already own, but they are rarely truly free once you count electricity, throughput limits, and engineering time.
Pricing math, in your inbox.
One short note a week on AI pricing, token economics, and margin. No spam, unsubscribe anytime.