LLM Economics
Token math, model selection, and the true unit cost of every generation.
Page 7 of 8
 LLM Economics
Gemini 3.5 Flash Gets Computer Use: What It Means for Agent Costs
Putting agentic computer use in a budget-tier model can cut cost per step, but total agent cost depends on how many steps a task takes, so cheaper per token does not always mean cheaper per job.
 LLM Economics
GPU Cloud Providers in Europe 2026: The Real Cost of Data Residency
European GPU clouds offer B200 and H200 capacity with EU data residency and sovereignty, but residency usually carries a price premium that you should model as part of cost per token, not treat as a free checkbox.
 LLM Economics
Custom AI Chips vs NVIDIA in 2026: What It Means for Your Inference Cost
Hyperscaler custom chips like Trainium, Google TPU, Maia, and Meta MTIA are built to cut the provider's cost of serving AI, but that only lowers your bill if it shows up as a cheaper per-token price or GPU-hour rate.
 LLM Economics
Oracle Cloud GPU Pricing in 2026: H100 vs H200 vs B200 Per-Hour Cost
Oracle Cloud prices H100, H200, and B200 GPUs at different per-hour rates, but the cheapest choice depends on your model size and utilization, not on which chip is newest.
 LLM Economics
TPU 8i vs NVIDIA Rubin and B200: Cost Per Token for LLM Inference (2026)
The accelerator with the best benchmark is not always the cheapest per token, because cost per token depends on price per hour, real throughput, and how much migration and lock-in you have to amortize.
 LLM Economics
NVIDIA B200 Cloud Pricing in 2026: How to Compare Per-Hour GPU Costs
B200 rental prices vary widely across clouds, so the number that matters is not dollars per hour but dollars per million tokens once you factor in throughput and utilization.
 LLM Economics
LLM Inference Cost at Scale: Napkin Math for Founders
To estimate LLM inference cost, multiply tokens per request by requests per month by your blended price per million tokens, then stress-test each assumption before you trust the total.
 LLM Economics
Why the Cheapest LLM Provider Won't Save Your Margins
Switching to the cheapest LLM provider rarely rescues a thin margin, because your token volume and product design drive cost far more than a lower headline $/1M-token rate.
 LLM Economics
What a $150M/Month Compute Deal Says About Your Token Costs
When an AI lab commits to about $150M a month for GPUs, that fixed cost has to be earned back through the tokens it sells, which is why your per-token price is really a bet on someone else's utilization.
 LLM Economics
What a $28B Neocloud Tells You About Your AI Token Costs
A neocloud is a GPU-only cloud built for AI compute, and when one reportedly clears $28B a year, it is a signal that the compute under your LLM bill is a large, fast-moving cost you should model as a variable, not a constant.
 LLM Economics
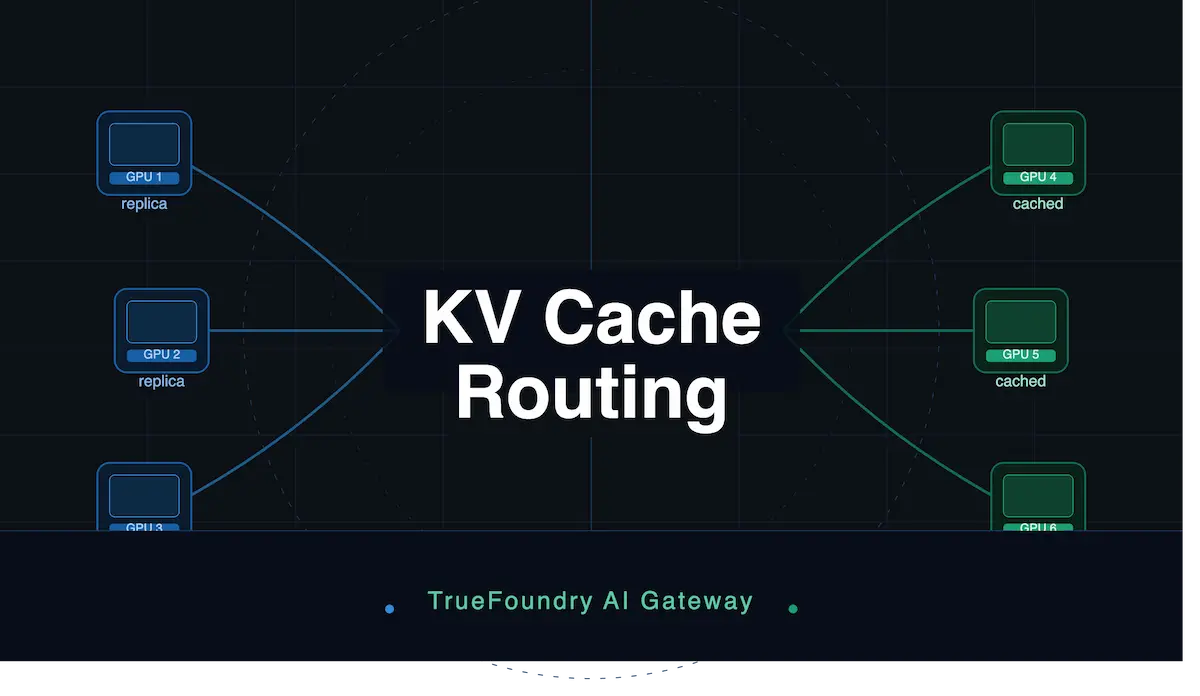
Your Load Balancer Is Quietly Inflating Your LLM Bill
Standard load balancers scatter requests across servers at random, which breaks prefix caching and makes you pay full price for tokens you already cached. Prefix-aware routing fixes it.
 LLM Economics
Governed AI Usage: How an AI Gateway Controls Token Spend
An AI gateway is a control plane that wraps every model request with identity, policy, safety, and observability, turning unpredictable token spend into a number you can govern and price against.
Pricing math, in your inbox.
One short note a week on AI pricing, token economics, and margin. No spam, unsubscribe anytime.